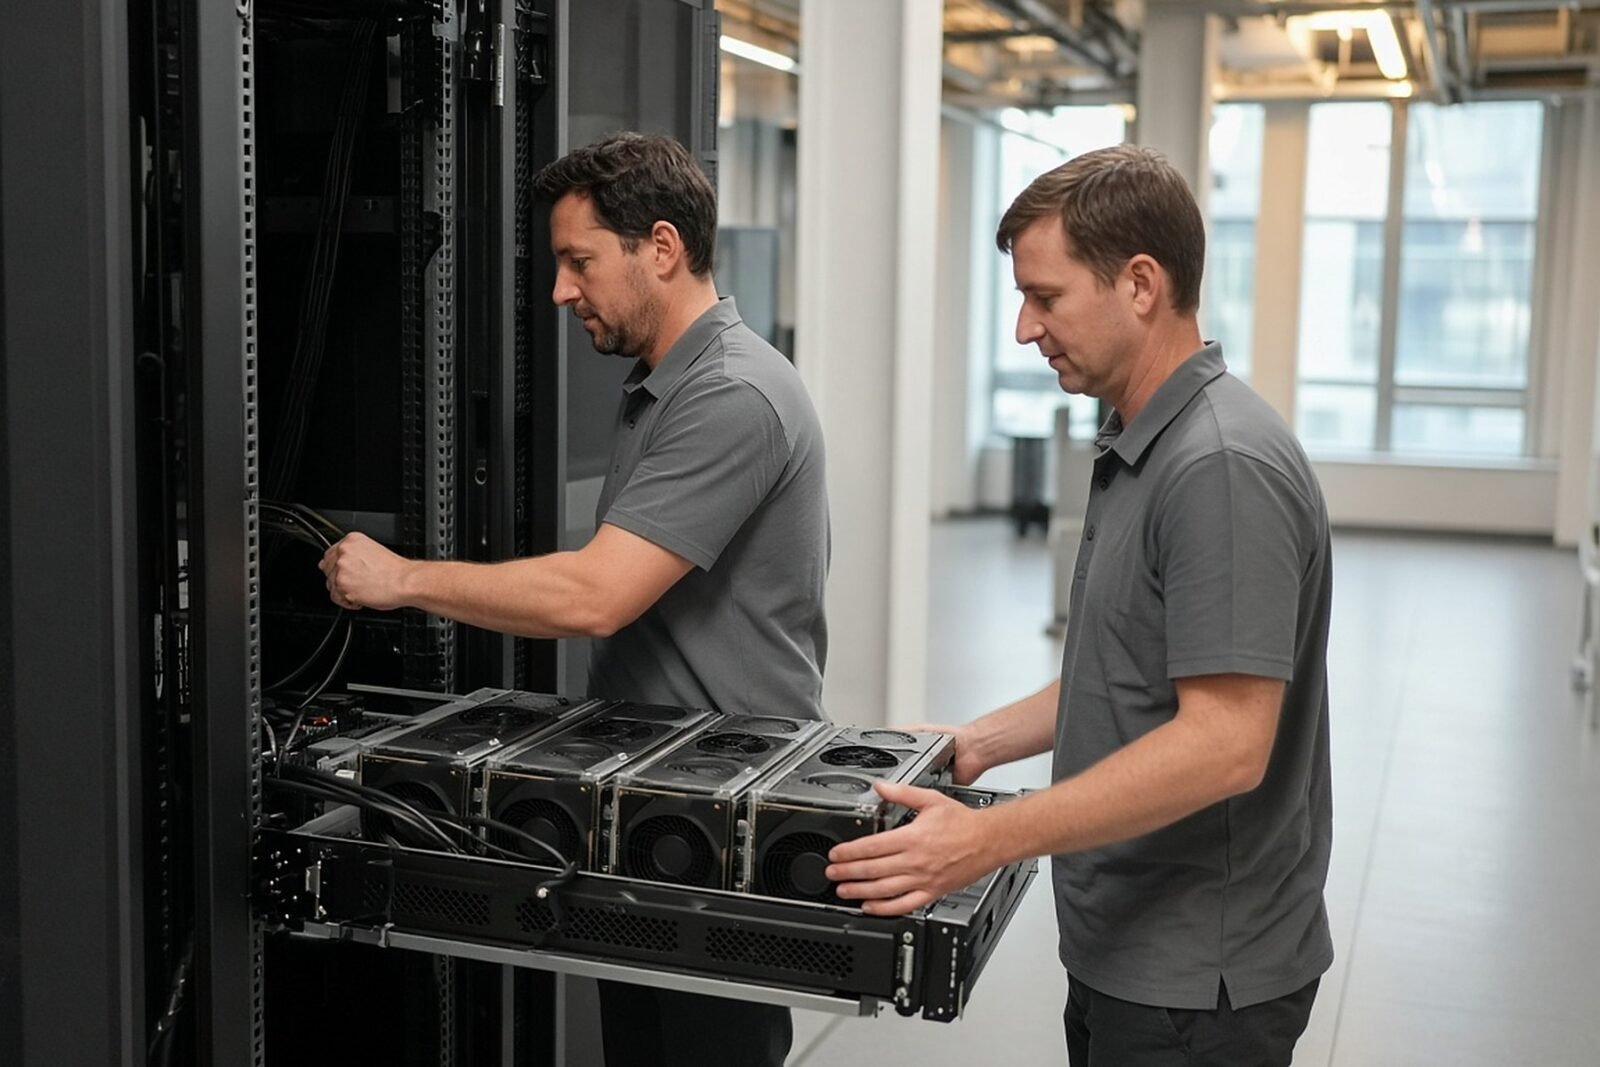
Tencent has put the full weights of Hy4, its flagship model, on Hugging Face. Tencent says the model reads images and video, operates a computer through the command line and on-screen apps, and writes game code for Unreal Engine, Unity and Godot. The catch is size: the smaller official checkpoint needs about 944 GB of GPU memory, or a server with eight top-end NVIDIA cards.
Hy4 is not new. Tencent launched it on November 4 in its own apps and API and promised the weights soon. They arrived on Friday, November 20, TechNode reported, as a chat model, an FP8 version (stored at lower precision to save memory) and a raw base model.
What Hy4 can do, according to Tencent
The Hy4 model card pitches it at office work more than chat. Feed it emails, documents, calendars and meeting notes, and Tencent says it will track projects, list action items and flag deadlines. Tencent also trained it on long jobs in Blender and CAD software.
The evidence is Tencent’s own. It says 213 finance professionals rated Hy4 first among open-weight models on 579 real tasks, and that its game development score rose 19.1% over the earlier preview. The tests are internal, and we could not check them.
Tencent’s two launch documents disagree on one figure. The model card says the hallucination rate (how often the model states false things as fact) fell from 15.76% to 5.45%. The Chinese launch post gives 12.95% to 7.2%. The card also admits a notable gap to top closed models in research-level math, long coding and hard visual questions.
What outside tests say
Artificial Analysis, which runs independent tests, scores Hy4 at 35 on its Intelligence Index. That is second among the 33 large open-weight models it compares, where the median is 23. It also calls Hy4 very wordy, with 160 million output tokens in testing against a median of 104 million.
It lists Tencent’s API at $0.83 per million input tokens and $2.50 per million output tokens, somewhat expensive for the class. Tencent’s TokenHub cloud bills Hy4 at half its list price until December 31. It lands in a busy month, after Mistral put its Large 4 weights online and Alibaba opened its Qwen4-Max API.
What it takes to run it
Hy4 is a mixture-of-experts model. Most of its layers hold 256 small expert networks, and a router sends every token (a word or part of one) to eight of them plus a shared expert. Only 49 billion of its 770 billion parameters work on each token, which keeps it quick. But all 770 billion must sit in memory.
The vLLM serving recipe asks for one 8-GPU NVIDIA node with about 944 GB of GPU memory for FP8, or 1,859 GB for the larger BF16 version. The FP8 files take 786 GB of disk. For something that fits on one machine, see our guide to small language models on a laptop.
Open, with a condition
TechNode called the release Apache 2.0, but the Hy4 license file says it is the Tencent Hy License, based on Apache 2.0 with extra commercial terms. A company selling general model access through an API needs a separate license from Tencent if its yearly revenue tops $50 million. The same applies before using Hy4 in a product with over 100 million monthly users.
Internal use is exempt if the model and its outputs stay in house. So are apps that use Hy4 for one narrow feature.
What to do this week
To see what Hy4 can do, try Tencent’s API or OpenRouter instead of downloading 786 GB. Give it one real task, like a messy spreadsheet or a small browser game, and compare the result and the answer length with your current model. Before hosting Hy4 for customers, read section 10 of the license.
Sources
Get the weekly email
The week's most useful AI news, a tutorial and an interview.

Lars Strother
Lars Strother is the senior editor for models and hardware at AI Observer, covering models and research, chips and hardware, and robotics. He came to journalism from engineering and still reads the benchmark tables before the press release. His coverage is measured and skeptical, and he wants to know what was tested, on what, and against which baseline.
Spotted a mistake? Tell us on the corrections page.